Code Optimization for Differential Equations
See this FAQ for information on common pitfalls and how to improve performance.
Code Optimization in Julia
Before starting this tutorial, we recommend the reader to check out one of the many tutorials for optimization Julia code. The following is an incomplete list:
- The Julia Performance Tips
- MIT 18.337 Course Notes on Optimizing Serial Code
- What scientists must know about hardware to write fast code
User-side optimizations are important because, for sufficiently difficult problems, most time will be spent inside your f function, the function you are trying to solve. “Efficient” integrators are those that reduce the required number of f calls to hit the error tolerance. The main ideas for optimizing your DiffEq code, or any Julia function, are the following:
- Make it non-allocating
- Use StaticArrays for small arrays
- Use broadcast fusion
- Make it type-stable
- Reduce redundant calculations
- Make use of BLAS calls
- Optimize algorithm choice
We'll discuss these strategies in the context of differential equations. Let's start with small systems.
Example Accelerating a Non-Stiff Equation: The Lorenz Equation
Let's take the classic Lorenz system. Let's start by naively writing the system in its out-of-place form:
function lorenz(u, p, t)
    dx = 10.0 * (u[2] - u[1])
    dy = u[1] * (28.0 - u[3]) - u[2]
    dz = u[1] * u[2] - (8 / 3) * u[3]
    return [dx, dy, dz]
end
lorenz (generic function with 1 method)Here, lorenz returns an object, [dx,dy,dz], which is created within the body of lorenz.
This is a common code pattern from high-level languages like MATLAB, SciPy, or R's deSolve. However, the issue with this form is that it allocates a vector, [dx,dy,dz], at each step. Let's benchmark the solution process with this choice of function:
import DifferentialEquations as DE
import BenchmarkTools: @btime
u0 = [1.0; 0.0; 0.0]
tspan = (0.0, 100.0)
prob = DE.ODEProblem(lorenz, u0, tspan)
@btime DE.solve(prob, DE.Tsit5());
1.651 ms (197817 allocations: 7.64 MiB)The BenchmarkTools.jl package's @benchmark runs the code multiple times to get an accurate measurement. The minimum time is the time it takes when your OS and other background processes aren't getting in the way. Notice that in this case it takes about 5ms to solve and allocates around 11.11 MiB. However, if we were to use this inside of a real user code, we'd see a lot of time spent doing garbage collection (GC) to clean up all the arrays we made. Even if we turn off saving, we have these allocations.
@btime DE.solve(prob, DE.Tsit5(); save_everystep = false); 1.417 ms (174910 allocations: 6.68 MiB)The problem, of course, is that arrays are created every time our derivative function is called. This function is called multiple times per step and is thus the main source of memory usage. To fix this, we can use the in-place form to make our code non-allocating:
function lorenz!(du, u, p, t)
    du[1] = 10.0 * (u[2] - u[1])
    du[2] = u[1] * (28.0 - u[3]) - u[2]
    du[3] = u[1] * u[2] - (8 / 3) * u[3]
    return
end
lorenz! (generic function with 1 method)Here, instead of creating an array each time, we utilized the cache array du. When the in-place form is used, DifferentialEquations.jl takes a different internal route that minimizes the internal allocations as well.
Notice that nothing is returned. When in in-place form, the ODE solver ignores the return. Instead, make sure that the original du array is mutated instead of constructing a new array
When we benchmark this function, we will see quite a difference.
u0 = [1.0; 0.0; 0.0]
tspan = (0.0, 100.0)
prob = DE.ODEProblem(lorenz!, u0, tspan)
@btime DE.solve(prob, DE.Tsit5());
455.363 μs (23062 allocations: 991.98 KiB)@btime DE.solve(prob, DE.Tsit5(); save_everystep = false); 262.208 μs (83 allocations: 4.27 KiB)There is a 16x time difference just from that change! Notice there are still some allocations and this is due to the construction of the integration cache. But this doesn't scale with the problem size:
tspan = (0.0, 500.0) # 5x longer than before
prob = DE.ODEProblem(lorenz!, u0, tspan)
@btime DE.solve(prob, DE.Tsit5(); save_everystep = false);
1.352 ms (83 allocations: 4.27 KiB)Since that's all setup allocations, the user-side optimization is complete.
Further Optimizations of Small Non-Stiff ODEs with StaticArrays
Allocations are only expensive if they are “heap allocations”. For a more in-depth definition of heap allocations, there are many sources online. But a good working definition is that heap allocations are variable-sized slabs of memory which have to be pointed to, and this pointer indirection costs time. Additionally, the heap has to be managed, and the garbage controllers has to actively keep track of what's on the heap.
However, there's an alternative to heap allocations, known as stack allocations. The stack is statically-sized (known at compile time) and thus its accesses are quick. Additionally, the exact block of memory is known in advance by the compiler, and thus re-using the memory is cheap. This means that allocating on the stack has essentially no cost!
Arrays have to be heap allocated because their size (and thus the amount of memory they take up) is determined at runtime. But there are structures in Julia which are stack-allocated. structs for example are stack-allocated “value-type”s. Tuples are a stack-allocated collection. The most useful data structure for DiffEq though is the StaticArray from the package StaticArrays.jl. These arrays have their length determined at compile-time. They are created using macros attached to normal array expressions, for example:
import StaticArrays: SA
A = SA[2.0, 3.0, 5.0]
typeof(A)
SVector{3, Float64} (alias for StaticArraysCore.SArray{Tuple{3}, Float64, 1, 3})Notice that the 3 after SVector gives the size of the SVector. It cannot be changed. Additionally, SVectors are immutable, so we have to create a new SVector to change values. But remember, we don't have to worry about allocations because this data structure is stack-allocated. SArrays have numerous extra optimizations as well: they have fast matrix multiplication, fast QR factorizations, etc. which directly make use of the information about the size of the array. Thus, when possible, they should be used.
Unfortunately, static arrays can only be used for sufficiently small arrays. After a certain size, they are forced to heap allocate after some instructions and their compile time balloons. Thus, static arrays shouldn't be used if your system has more than ~20 variables. Additionally, only the native Julia algorithms can fully utilize static arrays.
Let's ***optimize lorenz using static arrays***. Note that in this case, we want to use the out-of-place allocating form, but this time we want to output a static array:
function lorenz_static(u, p, t)
    dx = 10.0 * (u[2] - u[1])
    dy = u[1] * (28.0 - u[3]) - u[2]
    dz = u[1] * u[2] - (8 / 3) * u[3]
    return SA[dx, dy, dz]
end
lorenz_static (generic function with 1 method)To make the solver internally use static arrays, we simply give it a static array as the initial condition:
u0 = SA[1.0, 0.0, 0.0]
tspan = (0.0, 100.0)
prob = DE.ODEProblem(lorenz_static, u0, tspan)
@btime DE.solve(prob, DE.Tsit5());
211.526 μs (2657 allocations: 371.52 KiB)@btime DE.solve(prob, DE.Tsit5(); save_everystep = false); 170.985 μs (43 allocations: 2.91 KiB)And that's pretty much all there is to it. With static arrays, you don't have to worry about allocating, so use operations like * and don't worry about fusing operations (discussed in the next section). Do “the vectorized code” of R/MATLAB/Python and your code in this case will be fast, or directly use the numbers/values.
Example Accelerating a Stiff Equation: the Robertson Equation
For these next examples, let's solve the Robertson equations (also known as ROBER):
\[\begin{aligned} \frac{dy_1}{dt} &= -0.04y₁ + 10^4 y_2 y_3 \\ \frac{dy_2}{dt} &= 0.04 y_1 - 10^4 y_2 y_3 - 3×10^7 y_2^2 \\ \frac{dy_3}{dt} &= 3×10^7 y_2^2 \\ \end{aligned}\]
Given that these equations are stiff, non-stiff ODE solvers like DE.Tsit5 or DE.Vern9 will fail to solve these equations. The automatic algorithm will detect this and automatically switch to something more robust to handle these issues. For example:
import DifferentialEquations as DE
import Plots: plot
function rober!(du, u, p, t)
    y₁, y₂, y₃ = u
    k₁, k₂, k₃ = p
    du[1] = -k₁ * y₁ + k₃ * y₂ * y₃
    du[2] = k₁ * y₁ - k₂ * y₂^2 - k₃ * y₂ * y₃
    du[3] = k₂ * y₂^2
    return
end
prob = DE.ODEProblem(rober!, [1.0, 0.0, 0.0], (0.0, 1.0e5), [0.04, 3.0e7, 1.0e4])
sol = DE.solve(prob)
plot(sol, tspan = (1.0e-2, 1.0e5), xscale = :log10)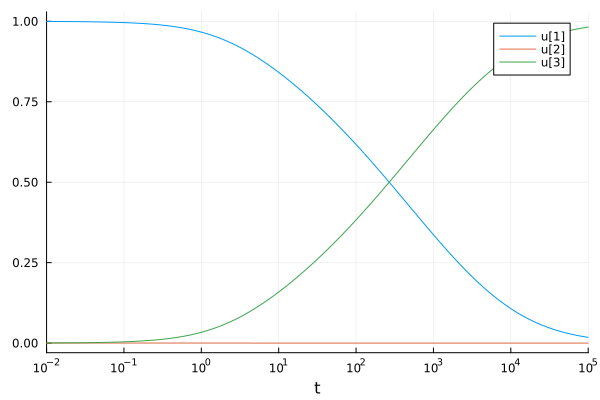
import BenchmarkTools: @btime
@btime DE.solve(prob);
67.532 μs (1831 allocations: 265.82 KiB)Choosing a Good Solver
Choosing a good solver is required for getting top-notch speed. General recommendations can be found on the solver page (for example, the ODE Solver Recommendations). The current recommendations can be simplified to a Rosenbrock method (Rosenbrock23 or Rodas5P, both from OrdinaryDiffEqRosenbrock; Rosenbrock23 and Rodas5P are in the default OrdinaryDiffEq re-export set, the rest of the Rosenbrock family — including Rodas5 — needs an explicit using OrdinaryDiffEqRosenbrock) for smaller (<50 ODEs) problems, ESDIRK methods for slightly larger (TRBDF2 or KenCarp4 from OrdinaryDiffEqSDIRK for <2000 ODEs), and QNDF (from OrdinaryDiffEqBDF) for even larger problems. lsoda from LSODA.jl is sometimes worth a try for the medium-sized category. Under DifferentialEquations.jl v8 the umbrella using DifferentialEquations only re-exports OrdinaryDiffEq's default solver set; non-default solvers must be imported from their host sublibrary.
More details on the solver to choose can be found by benchmarking. See the SciMLBenchmarks to compare many solvers on many problems.
From this, we try the recommendation of DE.Rosenbrock23() for stiff ODEs at default tolerances:
@btime DE.solve(prob, DE.Rosenbrock23()); 41.821 μs (669 allocations: 34.83 KiB)Declaring Jacobian Functions
In order to reduce the Jacobian construction cost, one can describe a Jacobian function by using the jac argument for the DE.ODEFunction. First we have to derive the Jacobian $\frac{df_i}{du_j}$ which is J[i,j]. From this, we get:
function rober_jac!(J, u, p, t)
    y₁, y₂, y₃ = u
    k₁, k₂, k₃ = p
    J[1, 1] = k₁ * -1
    J[2, 1] = k₁
    J[3, 1] = 0
    J[1, 2] = y₃ * k₃
    J[2, 2] = y₂ * k₂ * -2 + y₃ * k₃ * -1
    J[3, 2] = y₂ * 2 * k₂
    J[1, 3] = k₃ * y₂
    J[2, 3] = k₃ * y₂ * -1
    J[3, 3] = 0
    return
end
f! = DE.ODEFunction(rober!, jac = rober_jac!)
prob_jac = DE.ODEProblem(f!, [1.0, 0.0, 0.0], (0.0, 1.0e5), (0.04, 3.0e7, 1.0e4))
ODEProblem with uType Vector{Float64} and tType Float64. In-place: true
Non-trivial mass matrix: false
timespan: (0.0, 100000.0)
u0: 3-element Vector{Float64}:
1.0
0.0
0.0@btime DE.solve(prob_jac, DE.Rosenbrock23()); 35.381 μs (608 allocations: 31.98 KiB)Automatic Derivation of Jacobian Functions
But that was hard! If you want to take the symbolic Jacobian of numerical code, we can make use of ModelingToolkit.jl to symbolic-ify the numerical code and do the symbolic calculation and return the Julia code for this.
import ModelingToolkit as MTK
de = MTK.complete(MTK.modelingtoolkitize(prob))
\[ \begin{align} \frac{\mathrm{d}\mathtt{x_1}\left( t \right)}{\mathrm{d}t} &= - \mathtt{x_1}\left( t \right) ~ \mathtt{\alpha_1} + \mathtt{x_2}\left( t \right) ~ \mathtt{x_3}\left( t \right) ~ \mathtt{\alpha_3} \\ \frac{\mathrm{d}\mathtt{x_2}\left( t \right)}{\mathrm{d}t} &= \mathtt{x_1}\left( t \right) ~ \mathtt{\alpha_1} - \left( \mathtt{x_2}\left( t \right) \right)^{2} ~ \mathtt{\alpha_2} - \mathtt{x_2}\left( t \right) ~ \mathtt{x_3}\left( t \right) ~ \mathtt{\alpha_3} \\ \frac{\mathrm{d}\mathtt{x_3}\left( t \right)}{\mathrm{d}t} &= \left( \mathtt{x_2}\left( t \right) \right)^{2} ~ \mathtt{\alpha_2} \end{align} \]
We can tell it to compute the Jacobian if we want to see the code:
MTK.generate_jacobian(de)[2] # Second is in-place:(function (__argₛᵧₘ1187374493630987813, ___mtkunknowns___, ___mtkparameters___, __argₛᵧₘ7628082562247908723)
#= line 0 =# @inbounds begin
begin
begin
__mtk_arg_2 = begin
__miscₛᵧₘ0 = ___mtkparameters___[1]
end
__mtk_arg_3 = begin
__miscₛᵧₘ0 = ___mtkparameters___[2]
end
__mtk_arg_1 = begin
__miscₛᵧₘ0 = ___mtkunknowns___
end
local var"##cse#0" = __argₛᵧₘ1187374493630987813
__miscₛᵧₘ0 = 1
local var"##cse#1" = -1
local var"##cse#2" = __mtk_arg_2[1]
local var"##cse#3" = (*)(var"##cse#1", var"##cse#2")
__miscₛᵧₘ1 = 2
__miscₛᵧₘ2 = 3
local var"##cse#4" = 0
__miscₛᵧₘ3 = 4
local var"##cse#5" = __mtk_arg_2[3]
local var"##cse#6" = ___mtkunknowns___[3]
local var"##cse#7" = (*)(var"##cse#5", var"##cse#6")
__miscₛᵧₘ4 = 5
local var"##cse#8" = -2
local var"##cse#9" = ___mtkunknowns___[2]
local var"##cse#10" = __mtk_arg_2[2]
local var"##cse#11" = (*)(var"##cse#8", var"##cse#9", var"##cse#10")
local var"##cse#12" = (*)(var"##cse#1", var"##cse#5", var"##cse#6")
local var"##cse#13" = (+)(var"##cse#11", var"##cse#12")
__miscₛᵧₘ5 = 6
local var"##cse#14" = 2
local var"##cse#15" = (*)(var"##cse#14", var"##cse#9", var"##cse#10")
__miscₛᵧₘ6 = 7
local var"##cse#16" = (*)(var"##cse#9", var"##cse#5")
__miscₛᵧₘ7 = 8
local var"##cse#17" = (*)(var"##cse#1", var"##cse#9", var"##cse#5")
__miscₛᵧₘ8 = 9
__miscₛᵧₘ10 = #= line 0 =# @inbounds(begin
var"##cse#0"[__miscₛᵧₘ0] = var"##cse#3"
var"##cse#0"[__miscₛᵧₘ1] = var"##cse#2"
var"##cse#0"[__miscₛᵧₘ2] = var"##cse#4"
var"##cse#0"[__miscₛᵧₘ3] = var"##cse#7"
var"##cse#0"[__miscₛᵧₘ4] = var"##cse#13"
var"##cse#0"[__miscₛᵧₘ5] = var"##cse#15"
var"##cse#0"[__miscₛᵧₘ6] = var"##cse#16"
var"##cse#0"[__miscₛᵧₘ7] = var"##cse#17"
var"##cse#0"[__miscₛᵧₘ8] = var"##cse#4"
__miscₛᵧₘ9 = var"##cse#0"
end)
end
end
end
end)Now let's use that to give the analytical solution Jacobian:
prob_jac2 = DE.ODEProblem(de, [], (0.0, 1.0e5); jac = true)ODEProblem with uType Vector{Float64} and tType Float64. In-place: true
Initialization status: FULLY_DETERMINED
Non-trivial mass matrix: false
timespan: (0.0, 100000.0)
u0: 3-element Vector{Float64}:
1.0
0.0
0.0@btime DE.solve(prob_jac2); 204.356 μs (4594 allocations: 366.09 KiB)See the ModelingToolkit.jl documentation for more details.
Accelerating Small ODE Solves with Static Arrays
If the ODE is sufficiently small (<20 ODEs or so), using StaticArrays.jl for the state variables can greatly enhance the performance. This is done by making u0 a StaticArray and writing an out-of-place non-mutating dispatch for static arrays, for the ROBER problem, this looks like:
import StaticArrays: SA
function rober_static(u, p, t)
    y₁, y₂, y₃ = u
    k₁, k₂, k₃ = p
    du1 = -k₁ * y₁ + k₃ * y₂ * y₃
    du2 = k₁ * y₁ - k₂ * y₂^2 - k₃ * y₂ * y₃
    du3 = k₂ * y₂^2
    return SA[du1, du2, du3]
end
prob = DE.ODEProblem(
    rober_static, SA[1.0, 0.0, 0.0], (0.0, 1.0e5), SA[0.04, 3.0e7, 1.0e4]
)
sol = DE.solve(prob, DE.Rosenbrock23())
retcode: Success
Interpolation: specialized 2nd order "free" stiffness-aware interpolation
t: 61-element Vector{Float64}:
0.0
3.196206628740808e-5
0.00014400709669791316
0.00025605212710841824
0.0004859387252056149
0.0007179482298405133
0.0010819240431280998
0.0014801655696439712
0.0020679567767069714
0.0028435846274559493
⋮
25371.934242574636
30784.119976873913
37217.42637183452
44850.61378119758
53893.69155452613
64593.73799781128
77241.71960460563
92180.81944906653
100000.0
u: 61-element Vector{StaticArraysCore.SVector{3, Float64}}:
[1.0, 0.0, 0.0]
[0.9999987215181657, 1.2780900152625978e-6, 3.9181897521319503e-10]
[0.9999942397327672, 5.718510591908377e-6, 4.1756640838141946e-8]
[0.9999897579685716, 9.992106860321924e-6, 2.499245680985421e-7]
[0.99998056266788, 1.7833624284594363e-5, 1.603707835414181e-6]
[0.9999712826600025, 2.4034886076943867e-5, 4.682453920643881e-6]
[0.9999567250106862, 3.0390689558961375e-5, 1.2884299754832166e-5]
[0.999940798607161, 3.3884273738713e-5, 2.5317119100293923e-5]
[0.9999172960308617, 3.583508668595172e-5, 4.686888245237191e-5]
[0.9998862913719596, 3.6412401653671283e-5, 7.729622638673516e-5]
⋮
[0.055635077310007865, 2.3546320422346206e-7, 0.9443646872267856]
[0.0479253487640463, 2.0121495043224438e-7, 0.952074450021]
[0.04123342149003416, 1.7192788166891316e-7, 0.9587664065820815]
[0.03543699837030803, 1.4688361975260384e-7, 0.9645628547460702]
[0.030425371816164625, 1.254680931847298e-7, 0.9695745027157397]
[0.026099132201148605, 1.0715608431717384e-7, 0.9739007606427635]
[0.022369691694550085, 9.14984487616112e-8, 0.9776302168069984]
[0.019158563313533165, 7.811096380138722e-8, 0.9808413585754999]
[0.017827893850751696, 7.258919982166333e-8, 0.9821720335600455]If we benchmark this, we see a really fast solution with really low allocation counts:
@btime sol = DE.solve(prob, DE.Rosenbrock23()); 18.140 μs (171 allocations: 21.30 KiB)This version is thus very amenable to multithreading and other forms of parallelism.
Example Accelerating Linear Algebra PDE Semi-Discretization
In this tutorial, we will optimize the right-hand side definition of a PDE semi-discretization.
We highly recommend looking at the Solving Large Stiff Equations tutorial for details on customizing DifferentialEquations.jl for more efficient large-scale stiff ODE solving. This section will only focus on the user-side code.
Let's optimize the solution of a Reaction-Diffusion PDE's discretization. In its discretized form, this is the ODE:
\[\begin{align*} du &= D_1 (A_y u + u A_x) + \frac{au^2}{v} + \bar{u} - α u\\ dv &= D_2 (A_y v + v A_x) + a u^2 + β v \end{align*}\]
where $u$, $v$, and $A$ are matrices. Here, we will use the simplified version where $A$ is the tridiagonal stencil $[1,-2,1]$, i.e. it's the 2D discretization of the Laplacian. The native code would be something along the lines of:
import DifferentialEquations as DE, LinearAlgebra as LA
import BenchmarkTools: @btime
# Generate the constants
p = (1.0, 1.0, 1.0, 10.0, 0.001, 100.0) # a,α,ubar,β,D1,D2
N = 100
Ax = Array(
    LA.Tridiagonal(
        [1.0 for i in 1:(N - 1)],
        [-2.0 for i in 1:N],
        [1.0 for i in 1:(N - 1)]
    )
)
Ay = copy(Ax)
Ax[2, 1] = 2.0
Ax[end - 1, end] = 2.0
Ay[1, 2] = 2.0
Ay[end, end - 1] = 2.0

function basic_version!(dr, r, p, t)
    a, α, ubar, β, D1, D2 = p
    u = r[:, :, 1]
    v = r[:, :, 2]
    Du = D1 * (Ay * u + u * Ax)
    Dv = D2 * (Ay * v + v * Ax)
    dr[:, :, 1] = Du .+ a .* u .* u ./ v .+ ubar .- α * u
    dr[:, :, 2] = Dv .+ a .* u .* u .- β * v
    return
end

a, α, ubar, β, D1, D2 = p
uss = (ubar + β) / α
vss = (a / β) * uss^2
r0 = zeros(100, 100, 2)
r0[:, :, 1] .= uss .+ 0.1 .* rand.()
r0[:, :, 2] .= vss

prob = DE.ODEProblem(basic_version!, r0, (0.0, 0.1), p)
ODEProblem with uType Array{Float64, 3} and tType Float64. In-place: true
Non-trivial mass matrix: false
timespan: (0.0, 0.1)
u0: 100×100×2 Array{Float64, 3}:
[:, :, 1] =
11.0525 11.081 11.044 11.0974 … 11.0015 11.0685 11.0783 11.0434
11.0296 11.006 11.0367 11.081 11.0594 11.0327 11.0979 11.0559
11.0929 11.091 11.0426 11.0726 11.0313 11.0301 11.0523 11.0397
11.0298 11.0758 11.0858 11.0969 11.0674 11.0091 11.0505 11.0195
11.0783 11.0825 11.0061 11.0422 11.0211 11.0094 11.0125 11.0453
11.0884 11.0182 11.039 11.0821 … 11.0277 11.0111 11.0452 11.0933
11.0089 11.0101 11.0544 11.0614 11.0886 11.0102 11.0288 11.0606
11.0575 11.0712 11.0245 11.0011 11.0689 11.0474 11.0292 11.0982
11.0384 11.05 11.0364 11.0782 11.0679 11.0837 11.0868 11.0127
11.0709 11.087 11.0647 11.0129 11.0706 11.0022 11.0733 11.0383
⋮ ⋱
11.0112 11.0358 11.0679 11.0646 11.0636 11.0608 11.0407 11.074
11.0199 11.0248 11.0337 11.0532 11.0933 11.0112 11.0604 11.0539
11.0551 11.0125 11.0985 11.0335 11.083 11.0803 11.0918 11.0525
11.0671 11.0854 11.0337 11.0876 11.0626 11.0124 11.0118 11.0187
11.0234 11.0597 11.0529 11.0036 … 11.062 11.0862 11.0809 11.0057
11.0405 11.0713 11.0154 11.0579 11.0284 11.0251 11.0925 11.0252
11.0407 11.0243 11.0245 11.0743 11.0307 11.0455 11.0354 11.067
11.0258 11.0293 11.0364 11.0537 11.0992 11.0014 11.0635 11.0863
11.0569 11.08 11.0976 11.0233 11.0023 11.0749 11.0055 11.0083
[:, :, 2] =
12.1 12.1 12.1 12.1 12.1 12.1 … 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 … 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
⋮ ⋮ ⋱ ⋮
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 … 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1
12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1 12.1In this version, we have encoded our initial condition to be a 3-dimensional array, with u[:,:,1] being the A part and u[:,:,2] being the B part.
@btime DE.solve(prob, DE.Tsit5()); 35.601 ms (9267 allocations: 194.52 MiB)While this version isn't very efficient,
We recommend writing the “high-level” code first, and iteratively optimizing it!
The first thing that we can do is get rid of the slicing allocations. The operation r[:,:,1] creates a temporary array instead of a “view”, i.e. a pointer to the already existing memory. To make it a view, add @view. Note that we have to be careful with views because they point to the same memory, and thus changing a view changes the original values:
A = rand(4)
@show A
B = @view A[1:3]
B[2] = 2
@show A
4-element Vector{Float64}:
0.23951183402836562
2.0
0.151980887841626
0.6399101862783009Notice that changing B changed A. This is something to be careful of, but at the same time we want to use this since we want to modify the output dr. Additionally, the last statement is a purely element-wise operation, and thus we can make use of broadcast fusion there. Let's rewrite basic_version! to ***avoid slicing allocations*** and to ***use broadcast fusion***:
function gm2!(dr, r, p, t)
    a, α, ubar, β, D1, D2 = p
    u = @view r[:, :, 1]
    v = @view r[:, :, 2]
    du = @view dr[:, :, 1]
    dv = @view dr[:, :, 2]
    Du = D1 * (Ay * u + u * Ax)
    Dv = D2 * (Ay * v + v * Ax)
    @. du = Du + a .* u .* u ./ v + ubar - α * u
    @. dv = Dv + a .* u .* u - β * v
    return
end
prob = DE.ODEProblem(gm2!, r0, (0.0, 0.1), p)
@btime DE.solve(prob, DE.Tsit5());
30.639 ms (6972 allocations: 124.56 MiB)Now, most of the allocations are taking place in Du = D1*(Ay*u + u*Ax) since those operations are vectorized and not mutating. We should instead replace the matrix multiplications with LA.mul!. When doing so, we will need to have cache variables to write into. This looks like:
Ayu = zeros(N, N)
uAx = zeros(N, N)
Du = zeros(N, N)
Ayv = zeros(N, N)
vAx = zeros(N, N)
Dv = zeros(N, N)
function gm3!(dr, r, p, t)
    a, α, ubar, β, D1, D2 = p
    u = @view r[:, :, 1]
    v = @view r[:, :, 2]
    du = @view dr[:, :, 1]
    dv = @view dr[:, :, 2]
    LA.mul!(Ayu, Ay, u)
    LA.mul!(uAx, u, Ax)
    LA.mul!(Ayv, Ay, v)
    LA.mul!(vAx, v, Ax)
    @. Du = D1 * (Ayu + uAx)
    @. Dv = D2 * (Ayv + vAx)
    @. du = Du + a * u * u ./ v + ubar - α * u
    @. dv = Dv + a * u * u - β * v
    return
end
prob = DE.ODEProblem(gm3!, r0, (0.0, 0.1), p)
@btime DE.solve(prob, DE.Tsit5());
26.568 ms (3912 allocations: 31.09 MiB)But our temporary variables are global variables. We need to either declare the caches as const or localize them. We can localize them by adding them to the parameters, p. It's easier for the compiler to reason about local variables than global variables. ***Localizing variables helps to ensure type stability***.
p = (1.0, 1.0, 1.0, 10.0, 0.001, 100.0, Ayu, uAx, Du, Ayv, vAx, Dv) # a,α,ubar,β,D1,D2
function gm4!(dr, r, p, t)
    a, α, ubar, β, D1, D2, Ayu, uAx, Du, Ayv, vAx, Dv = p
    u = @view r[:, :, 1]
    v = @view r[:, :, 2]
    du = @view dr[:, :, 1]
    dv = @view dr[:, :, 2]
    LA.mul!(Ayu, Ay, u)
    LA.mul!(uAx, u, Ax)
    LA.mul!(Ayv, Ay, v)
    LA.mul!(vAx, v, Ax)
    @. Du = D1 * (Ayu + uAx)
    @. Dv = D2 * (Ayv + vAx)
    @. du = Du + a * u * u ./ v + ubar - α * u
    @. dv = Dv + a * u * u - β * v
    return
end
prob = DE.ODEProblem(gm4!, r0, (0.0, 0.1), p)
@btime DE.solve(prob, DE.Tsit5());
28.121 ms (1311 allocations: 30.88 MiB)We could then use the BLAS gemmv to optimize the matrix multiplications some more, but instead let's devectorize the stencil.
p = (1.0, 1.0, 1.0, 10.0, 0.001, 100.0, N)
function fast_gm!(du, u, p, t)
    a, α, ubar, β, D1, D2, N = p

    @inbounds for j in 2:(N - 1), i in 2:(N - 1)

        du[i, j, 1] = D1 *
            (
            u[i - 1, j, 1] + u[i + 1, j, 1] + u[i, j + 1, 1] + u[i, j - 1, 1] -
                4u[i, j, 1]
        ) +
            a * u[i, j, 1]^2 / u[i, j, 2] + ubar - α * u[i, j, 1]
    end

    @inbounds for j in 2:(N - 1), i in 2:(N - 1)

        du[i, j, 2] = D2 *
            (
            u[i - 1, j, 2] + u[i + 1, j, 2] + u[i, j + 1, 2] + u[i, j - 1, 2] -
                4u[i, j, 2]
        ) +
            a * u[i, j, 1]^2 - β * u[i, j, 2]
    end

    @inbounds for j in 2:(N - 1)
        i = 1
        du[1, j, 1] = D1 *
            (2u[i + 1, j, 1] + u[i, j + 1, 1] + u[i, j - 1, 1] - 4u[i, j, 1]) +
            a * u[i, j, 1]^2 / u[i, j, 2] + ubar - α * u[i, j, 1]
    end
    @inbounds for j in 2:(N - 1)
        i = 1
        du[1, j, 2] = D2 *
            (2u[i + 1, j, 2] + u[i, j + 1, 2] + u[i, j - 1, 2] - 4u[i, j, 2]) +
            a * u[i, j, 1]^2 - β * u[i, j, 2]
    end
    @inbounds for j in 2:(N - 1)
        i = N
        du[end, j, 1] = D1 *
            (2u[i - 1, j, 1] + u[i, j + 1, 1] + u[i, j - 1, 1] - 4u[i, j, 1]) +
            a * u[i, j, 1]^2 / u[i, j, 2] + ubar - α * u[i, j, 1]
    end
    @inbounds for j in 2:(N - 1)
        i = N
        du[end, j, 2] = D2 *
            (2u[i - 1, j, 2] + u[i, j + 1, 2] + u[i, j - 1, 2] - 4u[i, j, 2]) +
            a * u[i, j, 1]^2 - β * u[i, j, 2]
    end

    @inbounds for i in 2:(N - 1)
        j = 1
        du[i, 1, 1] = D1 *
            (u[i - 1, j, 1] + u[i + 1, j, 1] + 2u[i, j + 1, 1] - 4u[i, j, 1]) +
            a * u[i, j, 1]^2 / u[i, j, 2] + ubar - α * u[i, j, 1]
    end
    @inbounds for i in 2:(N - 1)
        j = 1
        du[i, 1, 2] = D2 *
            (u[i - 1, j, 2] + u[i + 1, j, 2] + 2u[i, j + 1, 2] - 4u[i, j, 2]) +
            a * u[i, j, 1]^2 - β * u[i, j, 2]
    end
    @inbounds for i in 2:(N - 1)
        j = N
        du[i, end, 1] = D1 *
            (u[i - 1, j, 1] + u[i + 1, j, 1] + 2u[i, j - 1, 1] - 4u[i, j, 1]) +
            a * u[i, j, 1]^2 / u[i, j, 2] + ubar - α * u[i, j, 1]
    end
    @inbounds for i in 2:(N - 1)
        j = N
        du[i, end, 2] = D2 *
            (u[i - 1, j, 2] + u[i + 1, j, 2] + 2u[i, j - 1, 2] - 4u[i, j, 2]) +
            a * u[i, j, 1]^2 - β * u[i, j, 2]
    end

    @inbounds begin
        i = 1
        j = 1
        du[1, 1, 1] = D1 * (2u[i + 1, j, 1] + 2u[i, j + 1, 1] - 4u[i, j, 1]) +
            a * u[i, j, 1]^2 / u[i, j, 2] + ubar - α * u[i, j, 1]
        du[1, 1, 2] = D2 * (2u[i + 1, j, 2] + 2u[i, j + 1, 2] - 4u[i, j, 2]) +
            a * u[i, j, 1]^2 - β * u[i, j, 2]

        i = 1
        j = N
        du[1, N, 1] = D1 * (2u[i + 1, j, 1] + 2u[i, j - 1, 1] - 4u[i, j, 1]) +
            a * u[i, j, 1]^2 / u[i, j, 2] + ubar - α * u[i, j, 1]
        du[1, N, 2] = D2 * (2u[i + 1, j, 2] + 2u[i, j - 1, 2] - 4u[i, j, 2]) +
            a * u[i, j, 1]^2 - β * u[i, j, 2]

        i = N
        j = 1
        du[N, 1, 1] = D1 * (2u[i - 1, j, 1] + 2u[i, j + 1, 1] - 4u[i, j, 1]) +
            a * u[i, j, 1]^2 / u[i, j, 2] + ubar - α * u[i, j, 1]
        du[N, 1, 2] = D2 * (2u[i - 1, j, 2] + 2u[i, j + 1, 2] - 4u[i, j, 2]) +
            a * u[i, j, 1]^2 - β * u[i, j, 2]

        i = N
        j = N
        du[end, end, 1] = D1 * (2u[i - 1, j, 1] + 2u[i, j - 1, 1] - 4u[i, j, 1]) +
            a * u[i, j, 1]^2 / u[i, j, 2] + ubar - α * u[i, j, 1]
        du[end, end, 2] = D2 * (2u[i - 1, j, 2] + 2u[i, j - 1, 2] - 4u[i, j, 2]) +
            a * u[i, j, 1]^2 - β * u[i, j, 2]
    end
    return
end
prob = DE.ODEProblem(fast_gm!, r0, (0.0, 0.1), p)
@btime DE.solve(prob, DE.Tsit5());
4.697 ms (699 allocations: 30.85 MiB)Notice that in this case fusing the loops and avoiding the linear operators is a major improvement of about 10x! That's an order of magnitude faster than our original MATLAB/SciPy/R vectorized style code!
Since this is tedious to do by hand, we note that ModelingToolkit.jl's symbolic code generation can do this automatically from the basic version:
import ModelingToolkit as MTK
function basic_version!(dr, r, p, t)
    a, α, ubar, β, D1, D2 = p
    u = r[:, :, 1]
    v = r[:, :, 2]
    Du = D1 * (Ay * u + u * Ax)
    Dv = D2 * (Ay * v + v * Ax)
    dr[:, :, 1] = Du .+ a .* u .* u ./ v .+ ubar .- α * u
    dr[:, :, 2] = Dv .+ a .* u .* u .- β * v
    return
end

a, α, ubar, β, D1, D2 = p
uss = (ubar + β) / α
vss = (a / β) * uss^2
r0 = zeros(100, 100, 2)
r0[:, :, 1] .= uss .+ 0.1 .* rand.()
r0[:, :, 2] .= vss

prob = DE.ODEProblem(basic_version!, r0, (0.0, 0.1), p)
de = MTK.complete(MTK.modelingtoolkitize(prob))

# Note jac=true,sparse=true makes it automatically build sparse Jacobian code
# as well!

fastprob = DE.ODEProblem(de, [], (0.0, 0.1); jac = true, sparse = true)
ODEProblem with uType Vector{Float64} and tType Float64. In-place: true
Initialization status: FULLY_DETERMINED
Non-trivial mass matrix: false
timespan: (0.0, 0.1)
u0: 20000-element Vector{Float64}:
11.084507035871026
11.05189278556751
11.078966738849292
11.088993742749755
11.05926690064694
11.050512552837237
11.01275645109538
11.047682563093787
11.067331411248611
11.06375529184205
⋮
12.100000000000001
12.100000000000001
12.100000000000001
12.100000000000001
12.100000000000001
12.100000000000001
12.100000000000001
12.100000000000001
12.100000000000001Lastly, we can do other things like multithread the main loops. LoopVectorization.jl provides the @turbo macro for doing a lot of SIMD enhancements, and @tturbo is the multithreaded version.
Optimizing Algorithm Choices
The last thing to do is then ***optimize our algorithm choice***. We have been using DE.Tsit5() as our test algorithm, but in reality this problem is a stiff PDE discretization and thus one recommendation is to use Sundials.CVODE_BDF(). However, instead of using the default dense Jacobian, we should make use of the sparse Jacobian afforded by the problem. The Jacobian is the matrix $\frac{df_i}{dr_j}$, where $r$ is read by the linear index (i.e. down columns). But since the $u$ variables depend on the $v$, the band size here is large, and thus this will not do well with a Banded Jacobian solver. Instead, we utilize sparse Jacobian algorithms. Sundials.CVODE_BDF allows us to use a sparse Newton-Krylov solver by setting linear_solver = :GMRES.
The Solving Large Stiff Equations tutorial goes through these details. This is simply to give a taste of how much optimization opportunity is left on the table!
Let's see how our fast right-hand side scales as we increase the integration time.
prob = DE.ODEProblem(fast_gm!, r0, (0.0, 10.0), p)
@btime DE.solve(prob, DE.Tsit5());
1.705 s (60133 allocations: 2.76 GiB)import Sundials: CVODE_BDF
@btime DE.solve(prob, CVODE_BDF(; linear_solver = :GMRES)); 414.333 ms (17700 allocations: 117.81 MiB)prob = DE.ODEProblem(fast_gm!, r0, (0.0, 100.0), p)
# Will go out of memory if we don't turn off `save_everystep`!
@btime DE.solve(prob, DE.Tsit5(); save_everystep = false); 3.211 s (103 allocations: 2.90 MiB)@btime DE.solve(prob, CVODE_BDF(; linear_solver = :GMRES); save_everystep = false); 1.225 s (44075 allocations: 2.49 MiB)prob = DE.ODEProblem(fast_gm!, r0, (0.0, 500.0), p)
@btime DE.solve(prob, CVODE_BDF(; linear_solver = :GMRES); save_everystep = false); 1.420 s (50897 allocations: 2.73 MiB)Notice that we've eliminated almost all allocations, allowing the code to grow without hitting garbage collection and slowing down.
Why is Sundials.CVODE_BDF doing well? What's happening is that, because the problem is stiff, the number of steps required by the explicit Runge-Kutta method grows rapidly, whereas Sundials.CVODE_BDF is taking large steps. Additionally, the GMRES linear solver form is quite an efficient way to solve the implicit system in this case. This is problem-dependent, and in many cases using a Krylov method effectively requires a preconditioner, so you need to play around with testing other algorithms and linear solvers to find out what works best with your problem.
Now continue to the Solving Large Stiff Equations tutorial for more details on optimizing the algorithm choice for such codes.