Continuous ESN: forecasting Lorenz
ContinuousESN is a continuous-time Echo State Network that implements the ODE of (Lukoševičius, 2012):
\[\dot{\mathbf{x}}(t) = -\mathbf{x}(t) + \tanh\!\left( \mathbf{W}_{\text{in}}\,\mathbf{u}(t) + \mathbf{W}_r\,\mathbf{x}(t) + \mathbf{b}\right)\]
This tutorial trains a ContinuousESN on Lorenz-63 data and rolls it forward autoregressively to reproduce the attractor. The training and prediction pipeline is the same as for ESN.
Building a Lorenz dataset
using ReservoirComputing
using LuxCore: setup
using SciMLBase
using DataInterpolations
using OrdinaryDiffEqTsit5
using Plots
using Random

Random.seed!(42)
rng = MersenneTwister(17)

function lorenz!(du, u, p, t)
    du[1] = p[1] * (u[2] - u[1])
    du[2] = u[1] * (p[2] - u[3]) - u[2]
    du[3] = u[1] * u[2] - p[3] * u[3]
end
data_prob = ODEProblem(
    lorenz!, [1.0, 0.0, 0.0], (0.0, 40.0), [10.0, 28.0, 8 / 3]
)
data = Array(solve(data_prob, Tsit5(); saveat = 0.02))

shift, train_len, predict_len = 300, 1000, 250
input_data = data[:, shift:(shift + train_len - 1)]
target_data = data[:, (shift + 1):(shift + train_len)]
test = data[:, (shift + train_len):(shift + train_len + predict_len - 1)]
3×250 Matrix{Float64}:
2.80893 1.80086 0.989378 … 11.4572 12.8061 14.014 14.9226
-2.77225 -2.72155 -2.62781 18.3428 19.2997 19.4236 18.4676
28.853 27.2322 25.7459 20.7774 24.1719 28.0071 31.9186Constructing the ContinuousESN
N_res = 300
res_radius = 0.9
res_sparsity = 6 / N_res

# Float64 initialisers so the reservoir, the solve, and the input all
# share a numeric type. Without these the cell would default to
# Float32 via `scaled_rand` / `rand_sparse` / `zeros32`.
init_input_f64(rng, d...) = scaled_rand(rng, Float64, d...)
init_reservoir_f64(rng, d...) = rand_sparse(
    rng, Float64, d...; radius = res_radius, sparsity = res_sparsity
)

esn_train = ContinuousESN(
    3, N_res, 3, (0.0, Float64(train_len)), Tsit5();
    init_input = init_input_f64,
    init_reservoir = init_reservoir_f64,
    state_modifiers = (NLAT2(),),
    reltol = 1.0e-6, abstol = 1.0e-8
)
esn_pred = ContinuousESN(
    3, N_res, 3, (0.0, Float64(predict_len)), Tsit5();
    init_input = init_input_f64,
    init_reservoir = init_reservoir_f64,
    state_modifiers = (NLAT2(),),
    reltol = 1.0e-6, abstol = 1.0e-8
)

ps, st = setup(rng, esn_train)
((reservoir = (input_matrix = [0.09788673589190573 -0.07588083719621236 -0.08293641400633676; 0.08201777970051705 0.07101102000504769 -0.04275530211568608; … ; -0.004903105741554193 0.07028390034205127 -0.023699563068035934; -0.014055019910847833 -0.059385745974936247 -0.02851243978484841], reservoir_matrix = [0.0 0.0 … 0.0 0.0; 0.0 0.0 … 0.0 0.0; … ; 0.0 0.0 … 0.0 0.0; 0.0 0.0 … 0.0 0.0]), state_modifiers = (NamedTuple(),), readout = (weight = Float32[0.22844005 0.68675387 … 0.45276093 0.60888493; 0.39494753 0.73264515 … 0.57383394 0.005248308; 0.43950975 0.31332195 … 0.5184448 0.42073524],)), (reservoir = (rng = Random.MersenneTwister(17, (0, 207210, 206208, 2, 204506, 522)),), state_modifiers = (NamedTuple(),), readout = NamedTuple()))Training
ps, st = train(esn_train, input_data, target_data, ps, st;
    objective = RidgeRegression(1.0e-6))
((reservoir = (input_matrix = [0.09788673589190573 -0.07588083719621236 -0.08293641400633676; 0.08201777970051705 0.07101102000504769 -0.04275530211568608; … ; -0.004903105741554193 0.07028390034205127 -0.023699563068035934; -0.014055019910847833 -0.059385745974936247 -0.02851243978484841], reservoir_matrix = [0.0 0.0 … 0.0 0.0; 0.0 0.0 … 0.0 0.0; … ; 0.0 0.0 … 0.0 0.0; 0.0 0.0 … 0.0 0.0]), state_modifiers = (NamedTuple(),), readout = (weight = [0.7236448832885105 0.4385693812283334 … -0.3689266965229517 -1.2841133231484807; 0.484366748022893 0.3051411295553555 … -2.554556472991559 -2.053364639354194; -1.229925258430508 0.2022361813307953 … 0.6981038820485366 4.628674168989397],)), (reservoir = (rng = Random.MersenneTwister(17, (0, 207210, 206208, 2, 204506, 522)), carry = ([-0.9964839968442868, -0.6629617338964505, -0.9920427016492703, 0.9991161881637612, 0.9951183632319044, 0.3813829744772827, 0.9062160084976781, 0.9974589969013458, -0.6560914810622281, 0.10449099082947172 … -0.9918521603301806, -0.9349414500929517, 0.9886902012802214, 0.4302627064938355, 0.8884714727362323, -0.9870666607510539, -0.9025471263278988, 0.17967620085530978, -0.8066868900325591, -0.7644717269773966],)), state_modifiers = (NamedTuple(),), readout = NamedTuple()))Autoregressive rollout
output, _ = predict(
    esn_pred, predict_len, ps, st; initialdata = test[:, 1]
)
([1.800740143771998 0.9891918017882311 … 9.431693813901436 10.92922277905825; -2.7217882184557824 -2.627699360189857 … 16.650351588863426 18.632646769109165; 27.231593245176928 25.745549382774673 … 15.1889736475821 17.904126859724713], (reservoir = (rng = Random.MersenneTwister(17, (0, 207210, 206208, 2, 204506, 522)), carry = ([-0.9774641703775059, 0.887489189028435, 0.476252581632235, 0.9082107827695337, 0.7992285849781301, -0.1230489528447357, 0.9808019877173203, 0.8913997193686393, -0.11338357461244547, -0.7896312147591273 … 0.03640799688495164, -0.6658154091135137, 0.601270126837399, 0.8062134743949131, 0.23309246559267494, -0.8723308621531485, -0.007728556580270788, 0.8412228808923328, 0.49219144471646925, -0.7341960001784541],)), state_modifiers = (NamedTuple(),), readout = NamedTuple()))using Plots.PlotMeasures
dt = 0.02
lorenz_maxlyap = 0.9056
lyap_time = (0:(predict_len - 1)) .* dt .* (1 / lorenz_maxlyap)
p1 = plot(lyap_time, [test[1, :] output[1, :]]; label = ["actual" "predicted"],
ylabel = "x(t)", linewidth = 2.5, xticks = false, yticks = -15:15:15);
p2 = plot(lyap_time, [test[2, :] output[2, :]]; label = ["actual" "predicted"],
ylabel = "y(t)", linewidth = 2.5, xticks = false, yticks = -20:20:20);
p3 = plot(lyap_time, [test[3, :] output[3, :]]; label = ["actual" "predicted"],
ylabel = "z(t)", linewidth = 2.5, xlabel = "max(λ)*t", yticks = 10:15:40);
plot(p1, p2, p3; plot_title = "Lorenz System Coordinates",
layout = (3, 1), xtickfontsize = 12, ytickfontsize = 12, xguidefontsize = 15,
yguidefontsize = 15,
legendfontsize = 12, titlefontsize = 20)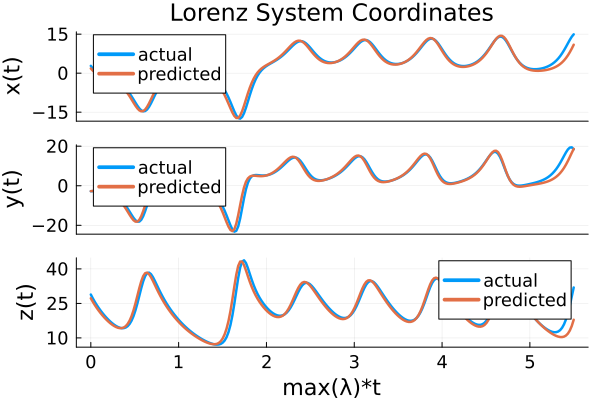
The two trajectories agree on the early portion of the rollout before chaotic divergence dominates — the same behaviour the discrete-ESN tutorial produces. The point of the example is that nothing in the training loop changes between discrete ESN, SciMLProblemReservoir with hand-rolled equations, and ContinuousESN: the same train / predict pipeline drives all three.
When to reach for ContinuousESN vs SciMLProblemReservoir
ContinuousESNpre-bakes the continuous ESN ODE; use it when the standard continuous ESN is what you want.SciMLProblemReservoiris the generic building block; use it when the reservoir ODE is not the standard eq (5) — bespoke RHS, SDE, DDE, or non-standard parameter layout.